
A useful log tells you which request failed and what your application was doing when it happened. A Node.js logging library helps you record that context consistently, with severity levels and fields you can search when something goes wrong.
In this article, we’ll compare seven Node.js logging tools and work through examples of how to use them. The list includes Grafana Loki for storing and searching logs across services, plus a separate look at Bunyan and Tracer for existing projects.
Pino is a good starting point for services that need JSON logs with request context. Winston offers more control over individual destinations, while LogTape lets an application configure logging for the packages it uses. Here’s how the seven options compare:
| Tool | Role | Good fit for | Main consideration |
|---|---|---|---|
| Pino | Structured logger | Node.js services that send JSON logs to a collector | Redaction paths must match your records |
| tslog | JavaScript and TypeScript logger | Projects that want typed APIs and readable development logs | v5 requires ESM and Node.js 22 or later |
| Cabin.js | Request logging middleware | Express and Koa applications that need automatic request logging | Requires Axe and configuration for captured data |
| Winston | Logger with multiple transports | Applications that need different formats and thresholds per destination | Each transport adds configuration to maintain |
| Grafana Loki | Log aggregator | Teams that need to search logs across services | Needs a logger or collector to send it records |
| loglevel | Console wrapper | Small tools and browser code that need severity filtering | Structured output and remote delivery need extensions |
| LogTape | Logger with hierarchical categories | Reusable libraries whose consumers need control over logging | The application must configure sinks before logs appear |
The examples below cover the application-side setup. Loki also requires a running server or a Grafana Cloud stack.
Logging records events while an application runs. A log entry can contain a message, severity level, timestamp, and fields that connect it to a request or operation.
The following screenshot shows a runtime error caused by using document in a Node.js environment:
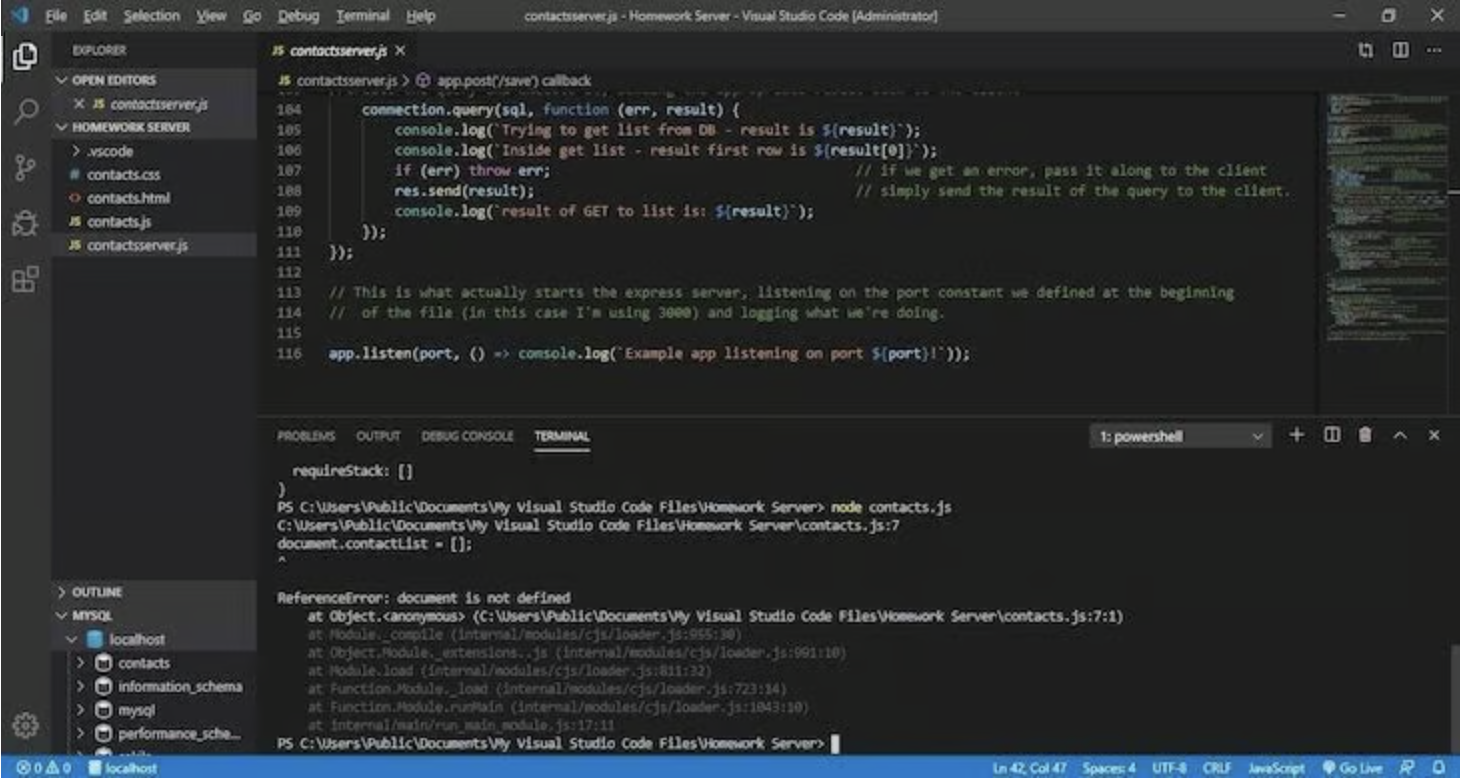
The stack trace points to the line that failed. For problems that depend on a particular request or sequence of events, logs can supply the context you need to reproduce the failure.
Node.js provides built-in console methods:
console.log('Server started');
console.warn('Request took longer than expected');
console.error('Failed to connect to the database');
During development, logging selected fields from an API response can help you inspect its shape:
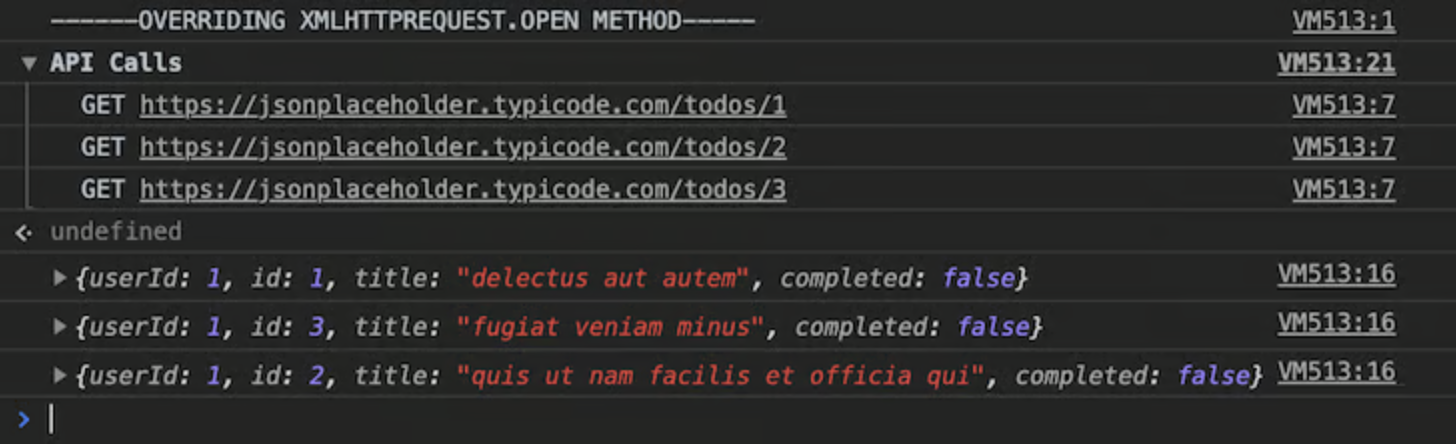
Choose those fields carefully because request bodies and responses can contain passwords, tokens, or personal information. Messages at the start and end of an operation can also help you follow asynchronous code and see how far a request got before it failed.
In production, consistent fields make logs easier to search across requests and services. A structured log record might look like this:
{
  "level": "error",
  "requestId": "abc123",
  "operation": "fetchUser",
  "message": "Failed to fetch user"
}
An aggregation platform can use the requestId to find related events. The exact field names vary by logger, so check its output schema when you configure log collection.
A logging library provides APIs for recording events and controlling their output. Common features include severity thresholds, structured fields, error serialization, and configurable destinations. Some libraries call destinations transports; LogTape calls them sinks.
A logger creates records within your application. An aggregator such as Loki receives records from multiple sources and makes them available for queries. Many production setups use both.
Follow Node.js logging best practices when choosing fields and severity levels. In an HTTP service, middleware is a useful place to attach request context and record when a response completes.
For example, Express middleware can collect request information before passing control to the next handler:
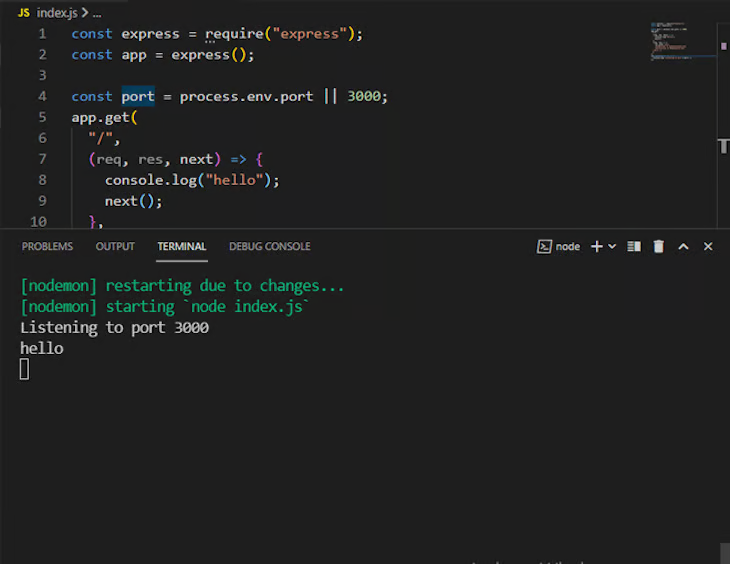
Use a request ID to connect messages from the same operation. Record useful details such as the route, status code, and elapsed time while excluding sensitive headers and payloads.
The examples use npm, though you can install the packages with other JavaScript package managers. Run the ESM examples in .mjs files or a project with "type": "module"; save CommonJS examples that use require() as .cjs files. The current tslog example requires Node.js 22 or later.
Pino writes structured JSON logs and supports child loggers, error serializers, and redaction. It is a useful starting point for a Node.js service that sends logs to a collector through standard output.
Install it with npm:
npm install pino
Or use Yarn:
yarn add pino
Pino includes trace, debug, info, warn, error, and fatal levels. JSON output gives a collector fields to parse; for local development, the separate pino-pretty package makes those records easier to scan.
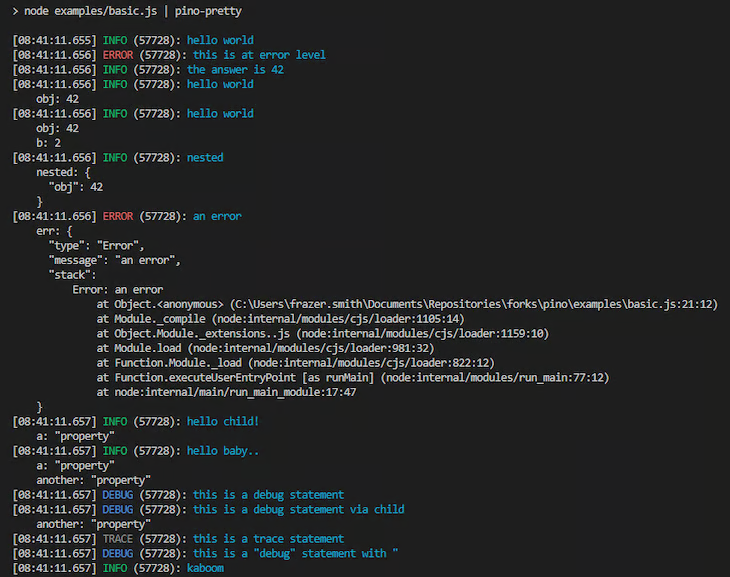
A child logger attaches fixed fields to subsequent messages:
import pino from 'pino';

const logger = pino({ level: 'info' });
const requestLogger = logger.child({ requestId: 'abc123' });

requestLogger.info('Processing request');
requestLogger.info({ operation: 'fetchUser' }, 'Fetching user');
requestLogger.error(
  { err: new Error('Database connection failed') },
  'Request failed'
);
Each record carries the request ID. Using the err field also invokes Pino’s standard error serializer.
Redaction paths must match your actual object structure. For example, this configuration covers selected top-level fields and a nested authorization header:
import pino from 'pino';

const logger = pino({
  redact: {
    paths: ['password', 'token', 'req.headers.authorization'],
    remove: true
  }
});

logger.info(
  {
    req: { headers: { authorization: 'Bearer example-token' } },
    operation: 'authenticate'
  },
  'Authentication attempted'
);
Pino applies these rules to the specified paths. Add paths for nested fields in your own records, and keep secrets out of message strings. Its redaction documentation covers path syntax and replacement values.
Pino works with Fastify, Express, and Node.js’s HTTP server. Its transport API runs log processing in a worker thread, which is useful when formatting or forwarding records would otherwise add work to the application thread.
tslog supports JavaScript and TypeScript with no runtime dependencies. It offers child loggers, masking, transports, and a choice of pretty or JSON output.
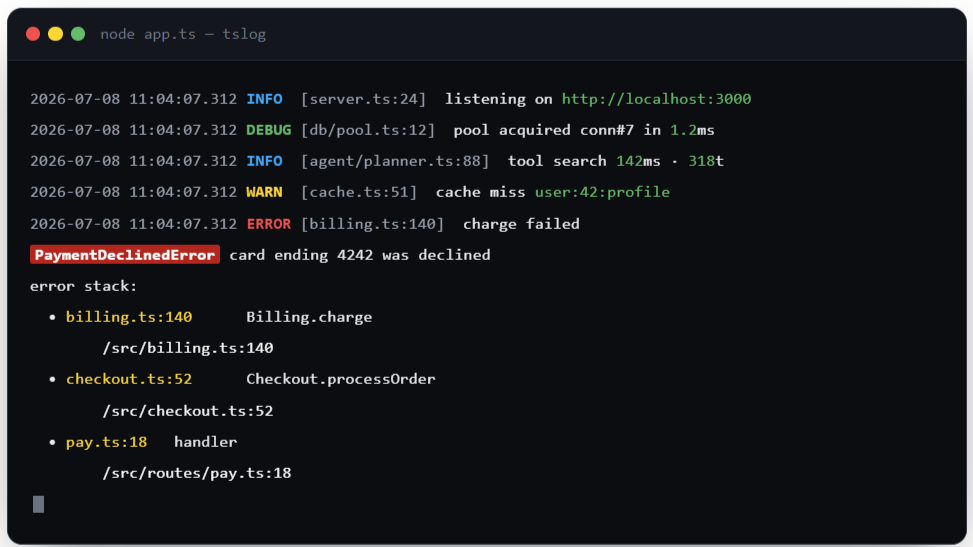
Install the v5 package:
npm install tslog@5
Current v5 releases require Node.js 22 or later and use ESM. Set type: 'json' when your collector expects structured JSON; the default output is pretty-printed:
import { Logger } from 'tslog';

const logger = new Logger({
  type: 'json',
  minLevel: 'INFO'
});

logger.debug('This message is below the configured threshold');
logger.info({ operation: 'startup' }, 'Server started');
logger.error(new Error('Database connection failed'));
The default levels are SILLY, TRACE, DEBUG, INFO, WARN, ERROR, and FATAL. In v5, fields passed as the first argument appear alongside the message in JSON output.
A sublogger inherits the parent configuration. Use bindings to attach a request ID to every record it writes:
const requestLogger = logger.getSubLogger({
  name: 'request',
  bindings: { requestId: 'abc123' }
});

requestLogger.info('Processing request');
requestLogger.info('Request completed');
The v5 release changes configuration, middleware, and the JSON schema. Existing v4 users should follow the migration guide and update downstream parsers before upgrading. Projects staying on v4 need examples written for that API.
Cabin.js adds request logging middleware for Express and Koa on top of Axe. Its documentation covers filtering sensitive data and forwarding logs to external services.
Cabin requires Axe as a peer dependency. Install Express too if you’re starting a new example:
npm install express axe cabin
Add the middleware before your routes:
const express = require('express');
const Axe = require('axe');
const Cabin = require('cabin');

const app = express();
const logger = new Axe();
const cabin = new Cabin({ logger });

app.use(cabin.middleware);

app.get('/', (req, res) => {
  res.send('OK');
});

app.listen(3000);
You can also supply a different logger to Axe. For example, install Signale:
npm install signale
Then replace the Axe initialization above with:
const { Signale } = require('signale');

const logger = new Axe({
  logger: new Signale()
});
Signale handles output in this configuration. Axe supplies the logging interface, and Cabin adds request metadata through middleware. External delivery requires the relevant integration setup.
Cabin is a good fit when automatic request logging would save you from writing middleware yourself. Review the metadata it captures and test its masking settings against the headers and payloads your application handles.
Cabin v14 declares Node.js 18 or later; the Axe v14 package used here requires at least Node.js 18.18. Use a supported Node.js release for deployment.
Winston lets you configure formats and destinations independently. It is useful when an application needs several transports with different thresholds, such as an error file and a combined application log.
Install it with:
npm install winston
This example adds timestamps and a service field to JSON records:
const winston = require('winston');

const logger = winston.createLogger({
  level: 'info',
  format: winston.format.combine(
    winston.format.timestamp(),
    winston.format.json()
  ),
  defaultMeta: { service: 'user-service' },
  transports: [
    new winston.transports.File({ filename: 'error.log', level: 'error' }),
    new winston.transports.File({ filename: 'combined.log' })
  ]
});

if (process.env.NODE_ENV !== 'production') {
  logger.add(new winston.transports.Console({
    format: winston.format.simple()
  }));
}

logger.info('Server started');
logger.error('Database connection failed');
Both file transports run in every environment. The condition adds console output outside production. The error.log file receives errors, while combined.log receives info and higher-severity messages.
Winston’s default npm levels use smaller numbers for higher severity:
const levels = {
  error: 0,
  warn: 1,
  info: 2,
  http: 3,
  verbose: 4,
  debug: 5,
  silly: 6
};
Winston also supports:
format.splat() for placeholders such as %sWhen logging Error objects, add format.errors({ stack: true }) before the JSON formatter to preserve the stack trace.
For long-running applications, plan how you’ll rotate and retain log files. A console transport with an external collector is often easier to manage in a container deployment.
Grafana Loki stores logs and supports queries through LogQL. Your Node.js logger produces records, and a transport or collector sends them to Loki.
You can run Loki yourself or use Grafana Cloud. For direct delivery from Pino, the community-maintained pino-loki transport supports batching, authentication, and labels:
npm install pino pino-loki
Configure the transport with your Loki host. This example enables basic authentication only when credentials are present:
import pino from 'pino';

const { LOKI_HOST, LOKI_USERNAME, LOKI_PASSWORD } = process.env;

if (!LOKI_HOST) {
  throw new Error('Set LOKI_HOST before starting the application');
}

if (Boolean(LOKI_USERNAME) !== Boolean(LOKI_PASSWORD)) {
  throw new Error('Set both LOKI_USERNAME and LOKI_PASSWORD');
}

const transport = pino.transport({
  target: 'pino-loki',
  options: {
    host: LOKI_HOST,
    ...(LOKI_USERNAME && LOKI_PASSWORD
      ? { basicAuth: { username: LOKI_USERNAME, password: LOKI_PASSWORD } }
      : {}),
    labels: {
      application: 'node-api',
      environment: process.env.NODE_ENV || 'development'
    }
  }
});

const logger = pino(transport);

logger.info('Server started');
logger.warn({ requestId: 'abc123' }, 'Request took longer than expected');
logger.error({ err: new Error('Database connection failed') }, 'Database error');
For a local instance, set LOKI_HOST to http://localhost:3100. With Grafana Cloud, use the host and credentials from your stack’s connection settings. The transport appends /loki/api/v1/push by default, so avoid putting that path in the host value as well.
Use labels for values with a small, bounded set of possibilities, such as service name and environment. Keep request IDs and other highly variable values in the log body or structured metadata. Too many unique label combinations can hurt Loki’s performance and storage efficiency.
For a separate collection pipeline, Grafana recommends Alloy. This lets you manage collection outside each application. Loki’s cost and query performance depend on your ingestion volume, retention, labels, and infrastructure.
If you use a direct transport, account for buffered records during shutdown and test what happens when Loki is unavailable. For services that already have a collector, sending structured logs to standard output may be simpler to operate.
loglevel wraps the available console with severity filtering. It works in browsers and Node.js and exposes trace, debug, info, warn, and error methods.
Install it with:
npm install loglevel
Set the threshold explicitly if you want informational messages. Its default is warn:
const log = require('loglevel');

log.setLevel('info');

log.info('Server started');
log.warn('Request took longer than expected');
log.error('Something went wrong');
Raise the threshold to suppress lower-severity messages:
log.setLevel('warn');
You can also create named loggers with independent levels through log.getLogger(name). Its plugin API allows extensions, but the core package does not provide the transport system or JSON schema of a structured application logger.
Choose loglevel when console-style output and level control meet your needs. If the project grows to require remote delivery or consistent request fields, account for the extra code or plugins you would need.
LogTape organizes loggers into hierarchical categories. Reusable libraries can emit records while the application decides which categories to enable and where output goes.
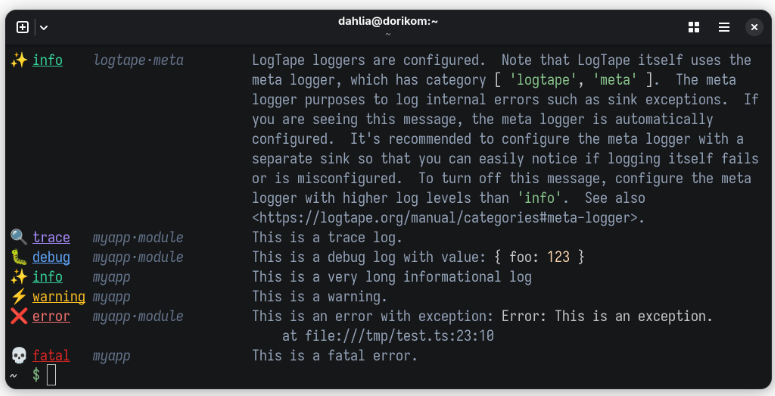
Install it with:
npm install @logtape/logtape
Configure a console sink at application startup. This example uses a JSON Lines formatter so attached properties are preserved in the output:
import {
  configure,
  getConsoleSink,
  getJsonLinesFormatter,
  getLogger
} from '@logtape/logtape';

await configure({
  sinks: {
    console: getConsoleSink({ formatter: getJsonLinesFormatter() })
  },
  loggers: [
    {
      category: ['my-app'],
      lowestLevel: 'debug',
      sinks: ['console']
    },
    {
      category: ['logtape', 'meta'],
      lowestLevel: 'warning',
      sinks: ['console']
    }
  ]
});

const logger = getLogger(['my-app']);

logger.info('Server started');
logger.info('Request completed', { requestId: 'abc123', statusCode: 200 });
LogTape’s levels are trace, debug, info, warning, error, and fatal. The ['logtape', 'meta'] configuration routes the library’s own diagnostics.
A nested category inherits configuration from its parent:
const databaseLogger = getLogger(['my-app', 'database']);

databaseLogger.debug('Connecting to database');
Add category-specific configuration when you want database debugging without the same verbosity elsewhere. The sink and formatter determine how structured properties appear in the final output.
Inside a reusable library, obtain a logger without configuring global output:
import { getLogger } from '@logtape/logtape';

const logger = getLogger(['my-library', 'database']);

export function connectToDatabase() {
  logger.debug('Connecting to database');
  // Add the database connection implementation here.
}
These calls produce no output until the host application configures a sink for the category. That gives package consumers control over how much logging they see and where the records go.
If your application already uses Bunyan or Tracer, review its logging requirements before planning a migration. Both have older published releases, so check their dependencies and run your integration against the Node.js version you deploy.
Bunyan writes JSON records and offers child loggers, serializers, streams, and a CLI for inspecting logs.
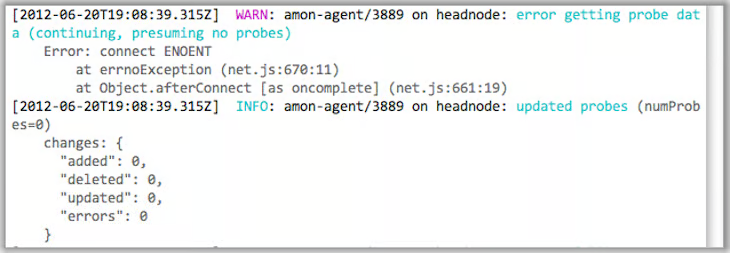
Install it with:
npm install bunyan
Create a named logger:
const bunyan = require('bunyan');

const logger = bunyan.createLogger({ name: 'server-app' });

logger.info('Server started');
logger.warn({ operation: 'fetchUser' }, 'Request took longer than expected');
Bunyan’s npm latest tag points to v1.8.15, published in January 2021. Its release history gives you a starting point for reviewing its maintenance status.
For an established Bunyan integration, consider whether migration would change field names, serializers, or the downstream queries your team relies on. For a new service, compare those requirements with Pino and Winston before committing.
Tracer provides configurable console output with source-file information, custom levels, and filters. Its transport callback can route records to destinations you implement.
Install it with:
npm install tracer
Use its logger methods as follows:
const logger = require('tracer').console();

logger.log('Server started');
logger.trace('Processing request');
logger.debug('Fetching user %s', '42');
logger.info('Request completed with status %d', 200);
logger.warn('Slow request: %j', { requestId: 'abc123', durationMs: 1200 });
logger.error('Database connection failed');
Tracer’s npm latest tag points to v1.3.0, published in October 2023. Check the release history and your runtime requirements when deciding whether to keep it.
An existing setup that relies on Tracer’s output format and call-site information may have little reason to change. If you’re adding structured request logs, compare the work involved with adopting Pino or Winston.
For a new Node.js service, I’d start with Pino if the goal is to write JSON logs with request context. Choose Winston when you need to route records to several destinations with different formats or severity thresholds.
tslog is worth considering for TypeScript projects that want readable development output and structured production logs, provided the application meets its v5 runtime requirements. LogTape suits reusable packages because their consumers can control logging through application-level configuration.
For Express and Koa, Cabin can save you work on request logging middleware. A small tool that only needs console output and level filtering may get everything it needs from loglevel.
Loki comes into the picture when you need to search logs across services. You can pair it with any suitable logger through a collector or supported transport.
Try your preferred logger with a request that succeeds and one that fails. Check whether the output contains enough context to follow each request through your application, then confirm those fields survive the trip to your log platform.
 Monitor failed and slow network requests in production
Deploying a Node-based web app or website is the easy part. Making sure your Node instance continues to serve resources to your app is where things get tougher. If you’re interested in ensuring requests to the backend or third-party services are successful, try LogRocket.
LogRocket lets you replay user sessions, eliminating guesswork around why bugs happen by showing exactly what users experienced. It captures console logs, errors, network requests, and pixel-perfect DOM recordings — compatible with all frameworks.
LogRocket's Galileo AI watches sessions for you, instantly identifying and explaining user struggles with automated monitoring of your entire product experience.
LogRocket instruments your app to record baseline performance timings such as page load time, time to first byte, slow network requests, and also logs Redux, NgRx, and Vuex actions/state. Start monitoring for free.
Learn key lessons from real-world code migrations using AI coding agents.
Compare the top AI development tools and models of November 2026. View updated rankings, feature breakdowns, and find the best fit for you.
AI coding assistants can generate UI quite quickly, but they don’t know your design system. Here’s how you can teach them the ins and outs.
Build a 3D hero with GPU Style Sheets and compare its code, bundle size, and rendering costs with Three.js.
Would you be interested in joining LogRocket's developer community?
Join LogRocket’s Content Advisory Board. You’ll help inform the type of content we create and get access to exclusive meetups, social accreditation, and swag.
Sign up now
 Learn more →