
TanStack AI 1.0 is out, and it is the first stable version of TanStack’s AI library. The release also brings a few big features. Subagents let one chat hand work to other agents, tool approvals make the app ask you before a tool runs, and compaction trims long chats so they stay within the model’s limit. It also has 23 provider adapters, so the same code can talk to OpenAI, Anthropic, Gemini, OpenRouter, and others.
To see if these features are valid, I built an app called Library Scout. It answers a question every React developer asks too often: which library should I use? Normally that means googling, opening npm, checking downloads, checking React support, checking the size, and then picking the one with the nicest logo anyway. Library Scout does the boring part for you.
The first Agent researcher pulls real numbers from npm, and a second agent, the writer, reads them and recommends one library. You stay in charge because the app asks for your permission before it searches.
I also built the same app with Vercel’s AI SDK 7, so we can compare them side by side. TanStack did not save me code, because it took 272 lines against 229 for the AI SDK. But it gave me features the AI SDK could not match, and I will show you what worked and what broke. The full code for both apps is in this GitHub repo, so you can check any file as we go.
You do not need a fancy setup to follow along. Here is what I used:
First, let us create a new React app. The TanStack CLI sets up the project for us, and then we add the AI packages the app needs. Run these in your terminal:
npx @tanstack/cli@latest create library-scout --framework React --package-manager pnpm --blank
cd library-scout
pnpm add --save-exact @tanstack/ai @tanstack/ai-react @tanstack/ai-client @tanstack/ai-openrouter zod
Put your key in a .env file as OPENROUTER_API_KEY. These commands installed @tanstack/ai 1.1.0 for me, and the AI SDK version used ai 7.0.162. Both apps use the openai/gpt-6-luna model through OpenRouter.
To keep costs favorable, I gave every model call a limit on how long its reply can be, using maxCompletionTokens. The problem is that gpt-6-luna likes to think quietly before it answers, and that hidden thinking counts toward the same limit. In one test, I set the limit to 300 tokens, and the model spent all 300 thinking. It thought very hard and then said nothing at all. That is why every call in this app also sets reasoning: 'off', which you will see in the code below.
Our agents need two tools that call free npm endpoints. searchNpm finds packages, and getPackageStats gets the numbers for one package. The two functions that call npm live in src/lib/npm.ts, which you can copy from the repo.
In the file src/lib/tools.ts, I define the tools there. This file has no server code, so the browser can use it too. Here is the search tool, the only one that needs your approval, and getPackageStatsDef sits below it in the same file:
export const searchNpmDef = toolDefinition({
  name: 'searchNpm',
  description: 'Search the npm registry. Returns package names, versions and descriptions.',
  inputSchema: z.object({ query: z.string().describe('Search words, for example "react toast"') }),
  needsApproval: true,
})
Next, I created src/lib/tools.server.ts. This file connects each tool to the function that does the work on the server:
export const searchNpmTool = searchNpmDef.server(searchNpm)
I went ahead to create src/routes/api.chat.ts. This is the server route the chat talks to. It sends the messages to the model and streams the reply back to the browser:
POST: async ({ request }) => {
  const params = await chatParamsFromRequest(request)
  const stream = chat({
    adapter: openRouterText(MODEL_MAIN),
    modelOptions: { maxCompletionTokens: 800 },
    reasoning: 'off',
    messages: params.messages,
    threadId: params.threadId,
    runId: params.runId,
  })
  return toServerSentEventsResponse(stream)
},
Now for the fun part. Each subagent has two pieces, and each piece gets its own file. I created src/lib/agents.ts for the first piece, a plain description of each agent’s name, job, tools, and input. It has no server code, so the browser can import it. The writer sits below the researcher in the same file:
export const researcher = {
  name: 'researcher',
  description: 'Researches npm packages for one focused task and returns findings with package names and real numbers.',
  inputSchema: z.object({
    task: z.string().describe('What to research. The researcher sees only this text.'),
  }),
  tools: [searchNpmDef, getPackageStatsDef],
} as const
Then I created src/lib/agents.server.ts for the second piece. Here, defineAgent() adds a run function that calls the model on the server. The writer gets the same treatment in this file, and the prompts are in the repo:
export const researcherAgent = defineAgent({
  ...researcher,
  run: (ctx) =>
    chat({
      adapter: openRouterText(MODEL_MAIN),
      modelOptions: { maxCompletionTokens: 1000 },
      reasoning: 'off',
      systemPrompts: [RESEARCHER_PROMPT],
      // On a resume, ctx.messages holds the child's own paused tool call. Without it the resume fails.
      messages: ctx.resume ? ctx.messages : [{ role: 'user', content: ctx.input.task }],
      tools: [searchNpmTool, getPackageStatsTool],
      ...ctx.forward, // threadId, runId, parentRunId, subagentRunId, resume, abortController
    }),
})
The lead does not need its own file, because it is just the chat() call in our route. Open src/routes/api.chat.ts to see where I added the subagents and some limits to that chat() call:
subagents: {
  agents: [researcherAgent, writerAgent],
  limits: { maxDepth: 1, maxConcurrent: 2, maxCalls: 4, timeoutMs: 120_000 },
},
The limits line lets the lead go one level deep, run two subagents at once, make four subagent calls per request, and give each one two minutes. I also checked the final browser bundle, and none of the prompts or server code leaked into it.
That one line is my favorite thing in TanStack AI. Here is what I wrote by hand for a smaller version in the AI SDK app. All of its agent code lives in one file, baseline-ai-sdk/src/lib/agents.server.ts in the repo, and each tool must also call countChildCall():
let childCalls = 0
const countChildCall = () => {
  if (++childCalls > 4) throw new Error('child limit reached (4 per request)')
}
// ...
stopWhen: stepCountIs(6),
// ...
function withChildLimits(abortSignal: AbortSignal | undefined) {
  const timeout = AbortSignal.timeout(120_000)
  return abortSignal ? AbortSignal.any([abortSignal, timeout]) : timeout
}
The AI SDK has no separate subagent API, so you call an agent from inside a tool, and streamChild is another helper I wrote:
const researcherTool = tool({
  description:
    'Researches npm packages for one focused task and returns findings with package names and real numbers.',
  inputSchema: z.object({ task: z.string().describe('What to research. The researcher sees only this text.') }),
  execute: async function* ({ task }, { abortSignal }) {
    countChildCall()
    yield* streamChild(researcher, task, abortSignal)
  },
  toModelOutput: ({ output }) => ({ type: 'text', value: lastText(output) }),
})
So did it work? Yes. When I asked which toast library suits a small dashboard, the lead called the researcher and then the writer in every completed run, and every download number in the answers matched npm.
On the browser side, useChat does most of the work. I created src/routes/chat.$chatId.tsx, where $chatId puts the chat ID in the URL. That ID becomes the threadId, so each conversation keeps its own history, and the agent descriptions give us types. Each subagent arrives as a message part with the type 'subagent', and we render a card for it:
const { messages, sendMessage, isLoading, stop, subagents, interrupts, resuming } = useChat({
  connection: fetchServerSentEvents('/api/chat'),
  threadId: chatId,
  subagents: scoutAgents, // declarations only: used for types, never run in the browser
  tools: [searchNpmDef], // types the approval interrupt for the child's searchNpm call
})
// ...
if (part.type === 'text') return <p key={index}>{part.content}</p>
if (part.type === 'subagent') return <SubagentCard key={part.subagent.id} subagent={part.subagent} />
Then create src/components/SubagentCard.tsx for the card itself:
export function SubagentCard({ subagent }: { subagent: SubagentHandle }) {
  return (
    <section className={`card ${subagent.status}`} data-name={subagent.name} data-status={subagent.status}>
      <header>
        <strong>{subagent.name}</strong>
        <span className="status">{subagent.status}</span>
        {subagent.status === 'running' && (
          <button type="button" className="stop" onClick={() => subagent.stop?.()}>
            Stop
          </button>
        )}
      </header>
      {subagent.error && <p className="error">{subagent.error.message}</p>}
      {subagent.messages.flatMap((message) =>
        message.parts.map((part, index) => {
          const key = `${message.id}-${index}`
          if (part.type === 'text') return <p key={key}>{part.content}</p>
          if (part.type === 'tool-call') {
            return (
              <div key={key} className="tool-call">
                <code>
                  {part.name}({part.arguments})
                </code>{' '}
                <em>{part.state}</em>
              </div>
            )
          }
          return null
        }),
      )}
    </section>
  )
}
The card shows the agent’s name, status, text, and tool calls, plus a Stop button that does not do what you think. We will get to that.
When I asked for one researcher per library, two cards started together and updated on their own, which looked great. Then the logs showed that both researchers had researched both libraries, so the work was done twice, very quickly.
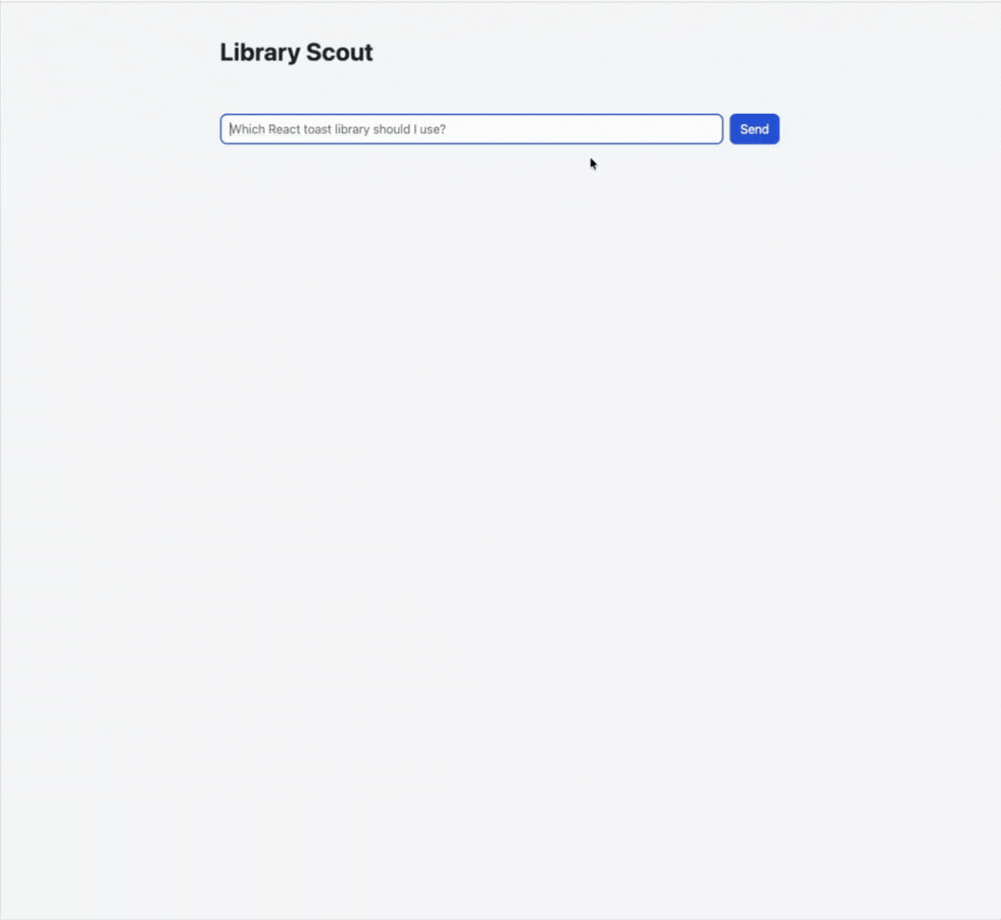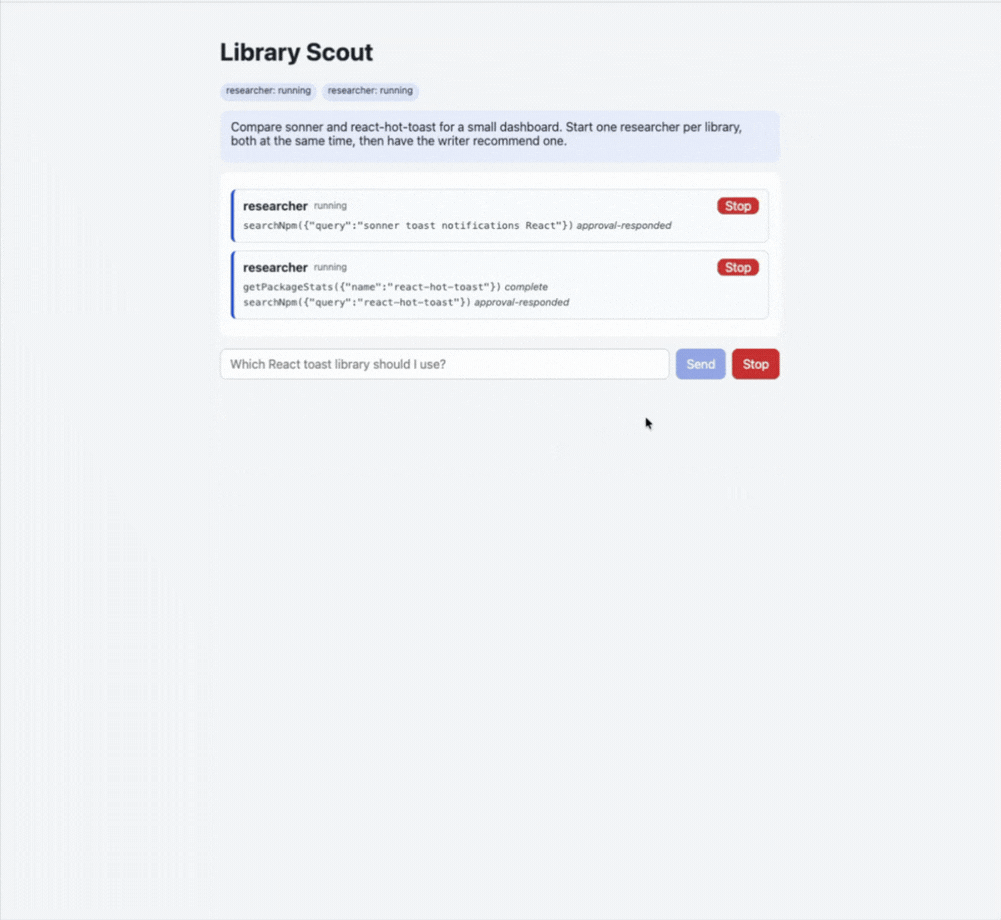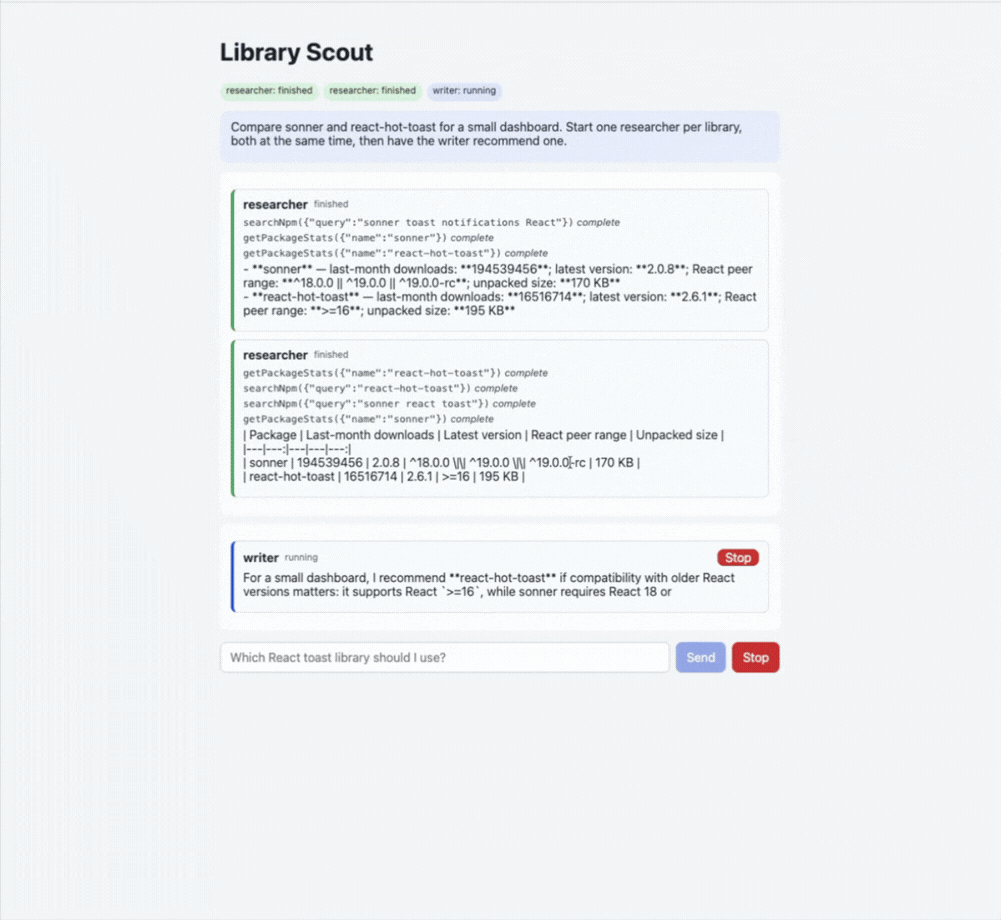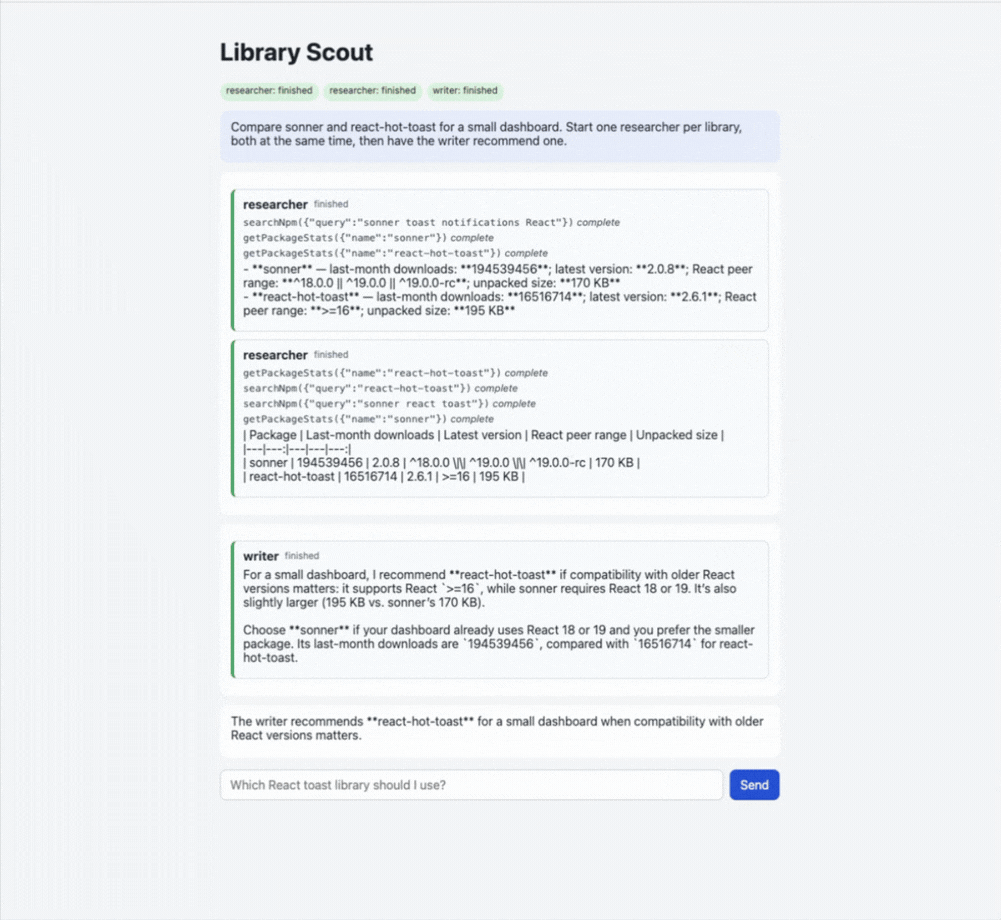
The AI SDK streams progress too, but I had to write each agent’s status myself, and it resends the whole agent message on every update. For the same question, the browser downloaded 1,447,308 bytes from it against 169,803 from TanStack.
When the researcher wants to run searchNpm, it pauses until you click Approve or Reject. The easy part to miss is that pausing ends the request, and clicking Approve sends a new one that must pick up where the old one stopped:
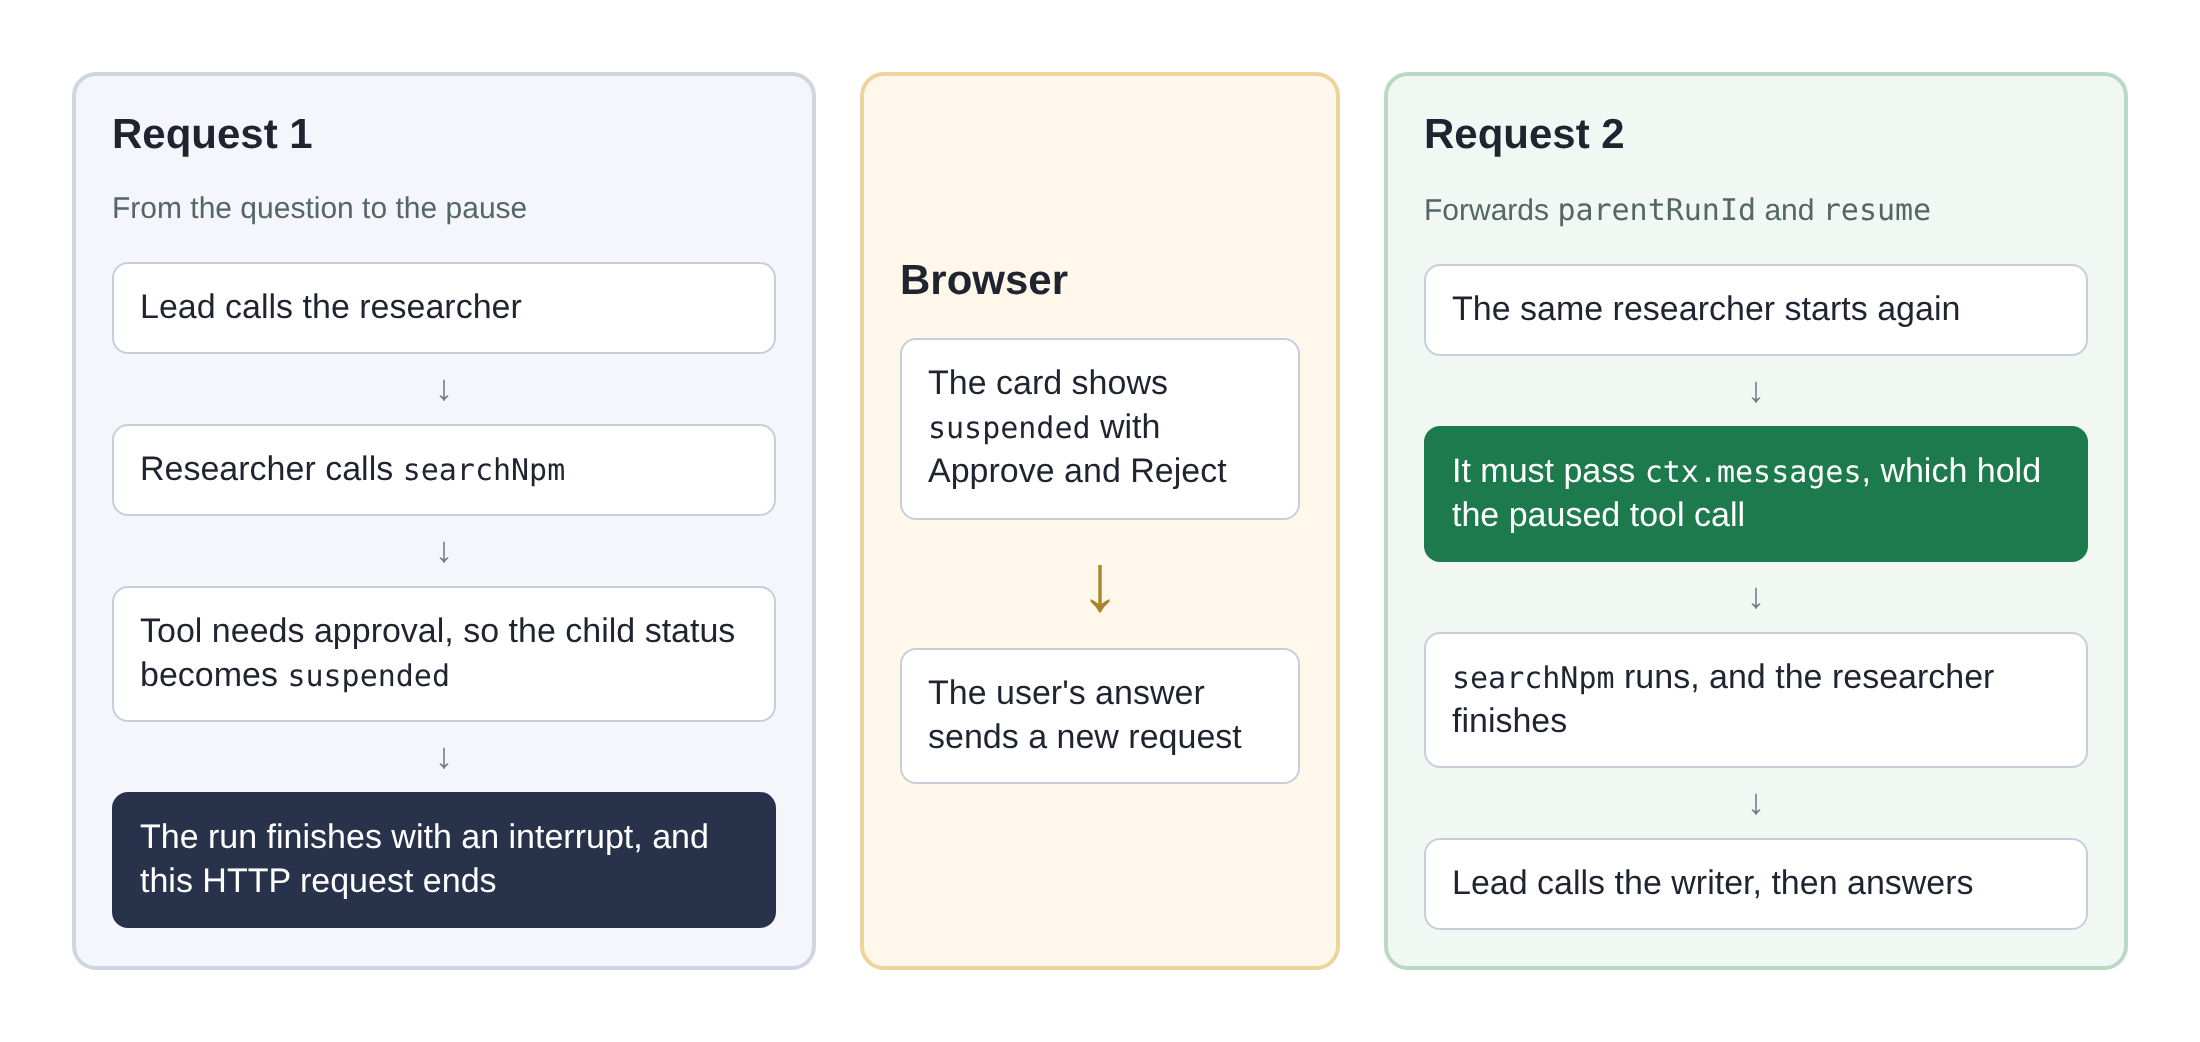
I learned this the hard way. My researcher copied the example in the subagents docs, which only sends the task text, and my very first Approve gave me this:
InterruptResumeValidationError: Resume entry references unknown interrupt approval_call_FINpuMRRhwDGfgE5fkMrQ1Hu. Resume entries must resolve or cancel the complete interrupt batch. One or more interrupt resolutions are invalid.
The researcher crashed, and the writer politely reported that it had nothing to recommend. The fix is the ctx.resume line in the researcher code. After your approval, the researcher needs its old messages, because they hold the search it was waiting to run, and the docs example leaves them out.
The server route also has to pass two values from the request to the lead. Open src/routes/api.chat.ts and add these to the lead’s chat() call:
...(params.parentRunId ? { parentRunId: params.parentRunId } : {}),
...(params.resume ? { resume: params.resume } : {}),
Forget parentRunId , and you get a clear error. Forget resume and you get no error at all, because the researcher just pauses again and you can click Approve forever.
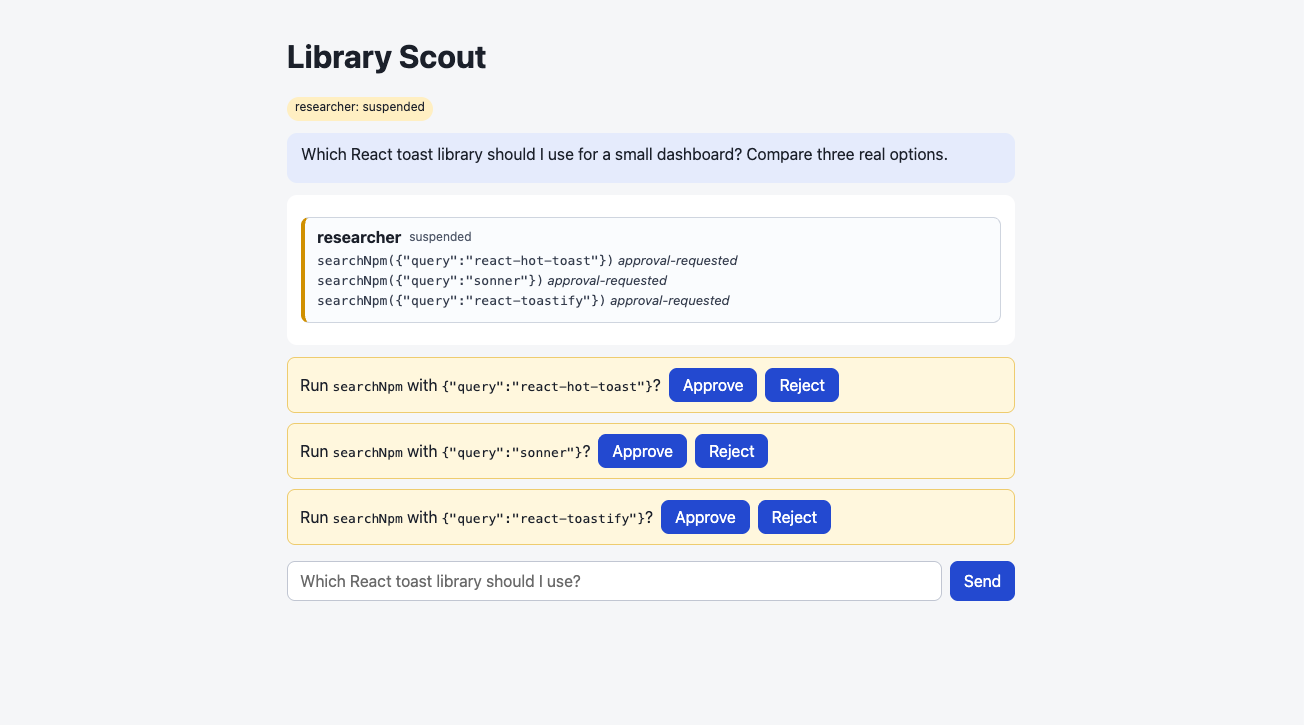
When the researcher asked for three searches at once, the docs buttons stayed clickable after I answered, and nothing was sent until all three had answers. Checking each request’s status fixed it. I added this to src/routes/chat.$chatId.tsx, below the messages:
{interrupts.map((interrupt) =>
  interrupt.kind === 'tool-approval' ? (
    <div key={interrupt.id} className="approval" data-status={interrupt.status}>
      <span>
        Run <code>{interrupt.toolName}</code> with <code>{JSON.stringify(interrupt.originalArgs)}</code>?
      </span>
      <button
        disabled={!interrupt.canResolve || resuming || interrupt.status !== 'pending'}
        onClick={() => interrupt.resolveInterrupt(true)}
      >
        Approve
      </button>
      {/* The Reject button is the same, with resolveInterrupt(false) */}
    </div>
  ) : null,
)}
A page reload normally loses a waiting search. Adding withPersistence(memoryPersistence()) took about 10 lines and brought it back after a reload, though a server restart still wipes it. With persistence on, 2 of my 20 resumes failed with Resume entry references non-pending interrupt, and I could not find out why.
The AI SDK cannot ask for approval inside a subagent, and its docs say so. When I tried anyway, the researcher stopped, the lead carried on as if all was fine, and searchNpm never ran. My workaround asks before the researcher starts:
toolApproval: { researcher: 'user-approval' },
That took 15 lines against 27 in TanStack, but you approve a general task, not the exact search.
I expected a card’s Stop button to stop that one agent, but it stops the whole run, so the lead never answers. The server does not even hear about it by default, and my stopped researcher kept working for five more seconds, made two more model calls, and finished an answer nobody would see.
This line makes the server stop when the browser does. Add it to the POST handler in src/routes/api.chat.ts, and pass the same abortController to chat(), as the repo does:
request.signal.addEventListener('abort', () => abortController.abort(), { once: true })
Now it stops everything, including the other researcher you did not touch, whose card keeps saying running anyway. There is also a cancelUrl option that I only found in the source code. It only works with the chat’s main Stop button, and you write the cancel route yourself, which is why my stop code took 38 lines in TanStack and 10 in the AI SDK.
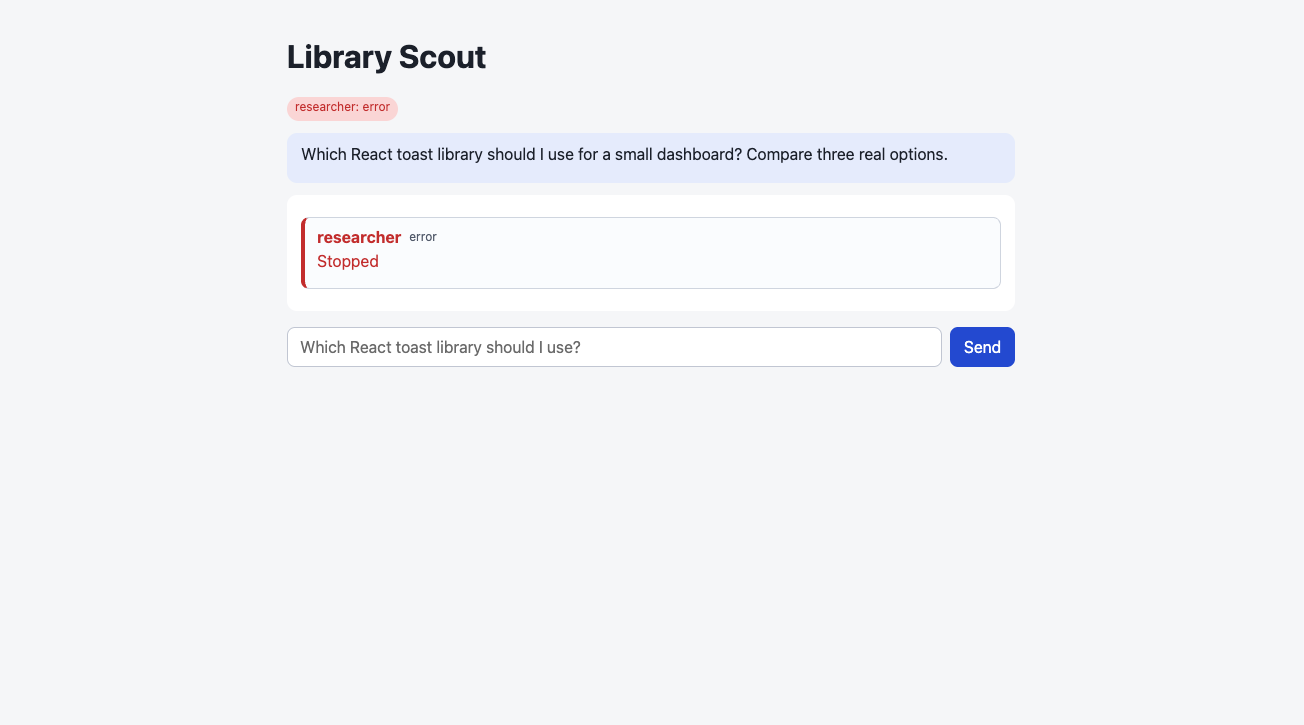
Neither library lets you stop one agent and keep the lead going. After a stop, my TanStack writer said it had no evidence, and the lead ignored it and replied, “Sonner would be my pick.” At least it was confident.
Long chats get expensive, because the model rereads the whole conversation every time. Compaction cuts what the model reads, while your screen still shows everything. I ran one five-message chat four times, with a 2,000-token limit per strategy. The first message said my project needs React 18 and a toast library under 5 KB, and the last one asked for those facts back:
| Setup | Tokens sent to the model | Cost | Remembered the first message? |
|---|---|---|---|
| No compaction | 17,055 | $0.00084 | Yes |
evictOldest |
6,587 | $0.00079 | No |
clearToolResults |
10,348 | $0.00086 | Yes |
summarizeOldest |
6,789 | $0.00163 | No |
summarizeOldest cost the most and then told me I “haven’t specified” either requirement, which is a bold thing to say to the person who specified them. clearToolResults kept the facts, so it went into the app, with 16 lines that include a small UI note. Add this near the top of src/routes/api.chat.ts, then put compaction in the lead’s middleware list:
const compaction = withCompaction({
  maxTokens: 1500,
  strategy: clearToolResults({ keepRecentToolResults: 2 }),
  onCompact: (info) =>
    console.log(
      `[compaction] ${info.before} -> ${info.after} tokens, ${info.messagesBefore} -> ${info.messagesAfter} messages`,
    ),
})
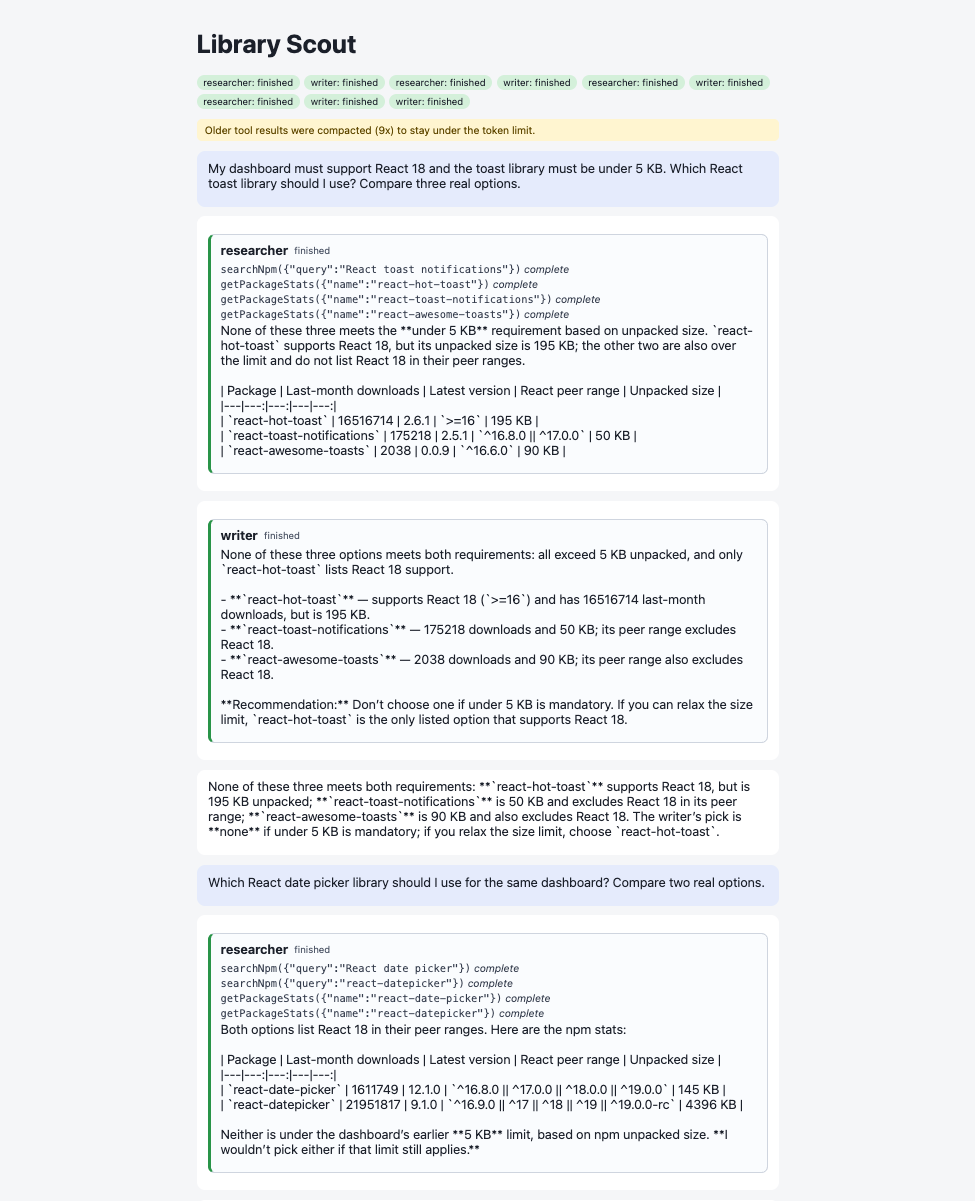
After five questions, every old card was still on screen and the model remembered my first message. But the last compaction only went from 3,353 tokens to 2,558, well over the 1,500 limit, so it slows the growth without stopping it.
Subagents need their own setup too. Compacting the lead did nothing for a subagent that reads the whole chat (2,888 tokens against 2,896), while giving a subagent its own withCompaction cut its last call from 3,819 tokens to 1,358.
I tried four kinds of switch. Most of the extra work came from the reply limit and reasoning level on every call:
| What I changed | Lines changed | What happened |
|---|---|---|
The model, from gpt-6-luna to anthropic/claude-haiku-5.5 |
1 | 6 type errors, but it ran |
The adapter, from openRouterText to openaiCompatible |
26 added, 22 removed | It ran with OpenRouter’s own option names |
| The direct Anthropic, OpenAI, and Gemini adapters | 16 to 22 added, 20 to 26 removed | Type checks only, because I only had an OpenRouter key |
| The lead’s model in the middle of a chat | 10 added, 2 removed | It worked |
The one-line change caused the most trouble. Haiku’s tool arguments came back broken five times across two runs, one run crashed, and the finished run cost 8.9 to 11 times more than gpt-6-luna. The same change in the AI SDK app had no type errors and passed its one run, so test a new model even when the change is tiny.
The openaiCompatible switch is sneakier. It accepts maxCompletionTokens and ignores it, so a reply limited to 16 tokens came back with 2,775. You need OpenRouter’s own option names. To try this switch, create src/lib/provider.server.ts:
export const openrouter = openaiCompatible({
  name: 'openrouter',
  baseURL: 'https://openrouter.ai/api/v1',
  apiKey: process.env.OPENROUTER_API_KEY!,
  models: [MODEL_MAIN],
})
Then change these two lines in every chat() call:
adapter: openrouter(MODEL_MAIN),
modelOptions: { max_tokens: 1000, reasoning: { effort: 'none' } }, // raw OpenRouter keys: maxCompletionTokens is ignored here
The TanStack and AI SDK columns come from my builds unless a cell says docs only. I did not build Mastra, so its column comes from its docs, and I cannot say how it feels to use:
| Feature | TanStack AI | AI SDK 7 | Mastra (docs only) |
|---|---|---|---|
| Approval inside a subagent | Built in | Not available | Built in |
| Status for each agent in the UI | Built in | Written by hand | Not confirmed |
| Stop one agent while the lead continues | No | No | Not documented |
| Limits | Built in, 1 line | Written by hand, 9 lines | Built in |
| Compaction | Built in | A helper plus your own code (docs only) | Built in |
| Saving chats | Built in | Your own code (docs only) | Built in |
| Lines for the same app | 272 | 229 | Not built |
| Gzipped browser JavaScript | 190,442 bytes | 155,678 bytes | Not built |
The last two rows are not a fair fight, because TanStack’s numbers include extras like approving each search. So does TanStack AI cut boilerplate? Not in line count for this app, but it cuts the number of features you build yourself.
TanStack is known for strong types and good docs. The types hold up. I made the same five mistakes in both apps, and each caught four before running. TanStack caught the fifth, a wrong subagent input sent through a router, while running, but the AI SDK let an unsupported temperature setting through with no warning at all.
The docs fall short. The approval example breaks on resume, the button example breaks with several approvals, and cancelUrl is missing. The AI SDK docs have mistakes too, such as using messages where the code expects uiMessages. And on lock-in, you are not stuck with one provider, but leaving one still takes work.
So my answer is yes on types and features, but not yet on docs or on how reliably approvals resume.
Pick TanStack AI when a person must approve what a subagent does, or when you want agent status, limits, compaction, and saved chats without building them yourself. Pick the AI SDK when your subagents only need to report back, when you switch models often, or when you want fewer lines and a smaller bundle right now.
These results come from about 30 TanStack runs and 3 AI SDK runs, mostly on one model, so test your own app before you decide.
TanStack AI 1.0 really does turn subagents into a library feature, and watching two researchers work side by side with so little code is fun. Just test three things before you trust them: what Stop stops, whether compaction holds its limit, and whether that one-line model switch is really one line.
Install LogRocket via npm or script tag. LogRocket.init() must be called client-side, not
server-side
$ npm i --save logrocket

// Code:

import LogRocket from 'logrocket';
LogRocket.init('app/id');
// Add to your HTML:

<script src="https://cdn.lr-ingest.com/LogRocket.min.js"></script>
<script>window.LogRocket && window.LogRocket.init('app/id');</script>
Learn key lessons from real-world code migrations using AI coding agents.
Compare the top AI development tools and models of November 2026. View updated rankings, feature breakdowns, and find the best fit for you.
AI coding assistants can generate UI quite quickly, but they don’t know your design system. Here’s how you can teach them the ins and outs.
Build a 3D hero with GPU Style Sheets and compare its code, bundle size, and rendering costs with Three.js.
Would you be interested in joining LogRocket's developer community?
Join LogRocket’s Content Advisory Board. You’ll help inform the type of content we create and get access to exclusive meetups, social accreditation, and swag.
Sign up now
 Learn more →